Authors
Philip Zetterberg
Software AI Engineer, TRENPEX
Contributors
Angie Zetterberg
Public relations, TRENPEX
Subscribe to our newsletter
Share
From Recognizing Individual Characters to Understanding Connections
A camera captures a passing freight car. The image shows a car number, technical markings, components, and possibly a container. For a human, it is often immediately clear which piece of information belongs to which object. For a computer system, however, these were long considered separate tasks.
Text recognition, also known as Optical Character Recognition (OCR for short), reads a license plate number, for example. Image classification assigns the vehicle to a category. A detection model identifies specific components in the image. Such specialized methods can perform their respective tasks very efficiently. However, the question of how the recognized information is related must often be answered using additional rules or software.
This is where vision-language models (VLMs for short) come into play. They link image information with language. As a result, a system can not only search for a number but also, for example, answer the question: “Which number belongs to the container on the front car?”
So the difference lies not so much in the fact that an image is being processed, but rather in the questions that can be asked about that image.
What is a vision-language model?
A vision-language model is an AI model that processes visual and linguistic information together. Simply put, it combines two capabilities: it can identify features in an image and relate them to terms, questions, or descriptions.
To do this, the image is first converted into a format that a neural network can process. A so-called vision encoder recognizes, for example, shapes, patterns, and spatial structures. You can think of it as the model’s visual perception system. A language model linked to the image features then processes the question asked and generates an appropriate answer. The specific technical implementation varies from model to model. [1–4]
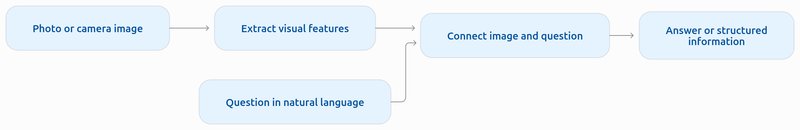
The key advancement is flexibility. While a traditional recognition task often requires a specially trained model or a fixed processing chain, a suitable VLM allows different tasks to be described in natural language. For example, one can first ask about the type of an object and then about its label or its visible state.
That doesn't mean the model "sees" like a human or understands everything correctly. It uses patterns it learned during training. Nevertheless, this approach opens up possibilities that go beyond mere object recognition.
Why Context Is Changing Image Processing
This advantage is particularly evident in text recognition. Traditional OCR is designed to reproduce as accurately as possible the characters appearing in an image. This is essential for identification numbers, labels, or technical inscriptions. However, OCR alone does not necessarily know the meaning of the text in the image.
A VLM can also take into account the relationship between text and its surroundings. If a nameplate contains multiple values, it can attempt to identify the correct value in response to the question, “What is the specified power output?” When capturing vehicle data, it can analyze various markings and their spatial relationships collectively.
This changes the task: “Read this text” becomes “Find the information I need and match it correctly.” Research on image-based questions and document comprehension shows how text, layout, and visual features can be used together to achieve this. [6, 7]
This is interesting even beyond the realm of text. For example, a VLM can be asked to identify visible components, their relationships to one another, or notable features in an image. Furthermore, language-based methods for recognizing open-ended object categories demonstrate that not every category necessarily has to be defined in a fixed list from the outset. Being able to identify a new category based solely on its description provides a significantly more flexible foundation for future applications. [2, 8]
New Opportunities for Industrial Applications
In industrial image processing, the focus is rarely on a single object. Images often contain a wealth of information that is only useful when viewed in context: Which unit is visible? Which number corresponds to it? Which components are present? Is there any visible distinguishing feature?
This is where VLMs open up new possibilities: They can establish connections between different pieces of information within an image and respond to questions that go beyond the mere recognition of individual features. For example, in the case of an industrial facility, one can ask not only which components are visible, but also how they are spatially arranged relative to one another or what clues the image provides about the facility’s condition. Information from documents, signs, or user interfaces can also be examined more closely within their respective contexts.
This capability is particularly interesting in situations where images vary greatly in appearance and information needs change over time. Linguistic approaches offer a more flexible way to access visual data than strictly predefined recognition categories alone can provide. This opens up new opportunities for the analysis, documentation, and support of industrial processes—without requiring every possible application to be defined in detail in advance.
Where precision remains crucial
These additional capabilities do not mean that VLMs automatically outperform every previous method. A model can accurately describe a scene and still overlook a single digit. When it comes to a technical identification number, even a single misrecognized character is significant.
Even with very small text, blurriness, varying lighting conditions, or unusual perspectives, image quality remains critical. Recent studies on multimodal text recognition and robustness make it clear that such challenges persist. [9–12]
Furthermore, a generative model can produce a convincing but incorrect answer—for example, by describing a feature that is not actually visible in the image. This phenomenon is known as hallucination. For this reason, technical statements on which subsequent processes rely should remain verifiable. [9]
After all, processing a larger model is often more computationally intensive than processing a small recognition network optimized for a specific task. In time-sensitive applications or on devices with limited computing power, this is an important selection criterion. [3, 4]
Outlook: Combining the Strengths of Both Approaches
The most exciting prospect is not necessarily to replace all existing methods with a single model. Rather, specialized detection and flexible image understanding can work together.
A model optimized for this purpose could continue to read an identification number quickly and accurately. A VLM could also combine information from different areas of an image, respond to new questions, or describe unusual situations. Technical checks would then ensure that only sufficiently reliable data is incorporated into automated processes.
As a result, computer vision is evolving from the recognition of individual features toward the context-based extraction of visual information. This is a particularly interesting prospect for industry: Camera images are not only becoming a source of individual measurement values or identifiers, but can increasingly be analyzed flexibly to provide the information that a process actually needs.
Vision-language models do not, therefore, mark a departure from traditional image processing. They represent the next step toward systems that can extract more information from images—and, in combination with specialized techniques, open up new possibilities for industrial automation.
References
¹Dosovitskiy, A. et al. (2021). An Image Is Worth 16×16 Words: Transformers for Image Recognition at Scale. ICLR. https://arxiv.org/abs/2010.11929
²Radford, A. et al. (2021). Learning Transferable Visual Models From Natural Language Supervision. ICML. https://arxiv.org/abs/2103.00020
³Li, J. et al. (2023). BLIP-2: Bootstrapping Language-Image Pre-training with Frozen Image Encoders and Large Language Models. ICML. https://arxiv.org/abs/2301.12597
⁴Liu, H. et al. (2023). Visual Instruction Tuning. NeurIPS. https://arxiv.org/abs/2304.08485
⁵Shi, B., Bai, X. & Yao, C. (2017). An End-to-End Trainable Neural Network for Image-Based Sequence Recognition and Its Application to Scene Text Recognition. IEEE TPAMI. https://doi.org/10.1109/TPAMI.2016.2646371
⁶Singh, A. et al. (2019). Towards VQA Models That Can Read. CVPR. https://arxiv.org/abs/1904.08920
⁷Kim, G. et al. (2022). OCR-free Document Understanding Transformer. ECCV. https://arxiv.org/abs/2111.15664
⁸Minderer, M. et al. (2022). Simple Open-Vocabulary Object Detection with Vision Transformers. ECCV. https://arxiv.org/abs/2205.06230
⁹Li, Y. et al. (2023). Evaluating Object Hallucination in Large Vision-Language Models. EMNLP. https://arxiv.org/abs/2305.10355
¹⁰Fu, L. et al. (2025). OCRBench v2: An Improved Benchmark for Evaluating Large Multimodal Models on Visual Text Localization and Reasoning. NeurIPS. https://arxiv.org/abs/2501.00321
¹¹Shi, B. et al. (2025). Scaling Vision Pre-Training to 4K Resolution. CVPR. https://arxiv.org/abs/2503.19903
¹²Saxena, R., Suglia, A. & Minervini, P. (2026). VLM-RobustBench: A Comprehensive Benchmark for Robustness of Vision-Language Models. https://arxiv.org/abs/2603.06148